Dive into Deep Learning
  • Slides
  • Courses
  • GitHub
  • Discuss
  • PDF
    • PyTorch
    • JAX
    • TensorFlow
    • MXNet
  • Notebooks
    • PyTorch
    • JAX
    • TensorFlow
    • MXNet
  1. index.html
  • index.html
  • Preface
    • Installation
    • Notation
    • Introduction
  • Basics
    • 1  Preliminaries
    • 1.1  Data Manipulation
    • 1.2  Data Preprocessing
    • 1.3  Linear Algebra
    • 1.4  Calculus
    • 1.5  Automatic Differentiation
    • 1.6  Probability and Statistics
    • 1.7  Documentation
    • 2  Linear Regression
    • 2.1  Linear Regression
    • 2.2  Object-Oriented Design for Implementation
    • 2.3  Synthetic Data
    • 2.4  Implementation from Scratch
    • 2.5  Concise Implementation
    • 2.6  Generalization
    • 2.7  Weight Decay
    • 3  Linear Classification
    • 3.1  Softmax Regression
    • 3.2  Image Classification Data
    • 3.3  Measuring Classifiers
    • 3.4  Softmax Regression from Scratch
    • 3.5  Concise Implementation
    • 3.6  Generalization in Classification
    • 3.7  Environment and Distribution Shift
    • 4  Multilayer Perceptron
    • 4.1  Multilayer Perceptrons
    • 4.2  Implementation
    • 4.3  Backpropagation
    • 4.4  Numerical Stability and Initialization
    • 4.5  Generalization in Deep Learning
    • 4.6  Dropout
    • 4.7  Predicting House Prices on Kaggle
    • 5  Computation
    • 5.1  Modules and Model Construction
    • 5.2  Parameters, State, and Memory
    • 5.3  Initialization
    • 5.4  Custom Layers and Functions
    • 5.5  Numerical Formats
    • 5.6  Saving, Loading, and Pretrained Weights
    • 5.7  GPUs, Devices, and Memory
    • 5.8  Reproducibility and Inspection
    • 6  Convolutional Neural Networks
    • 6.1  From Fully Connected Layers to Convolutions
    • 6.2  Convolutions for Images
    • 6.3  Padding, Stride, and Dilation
    • 6.4  Multiple Input and Multiple Output Channels
    • 6.5  Pooling
    • 6.6  Convolutional Neural Networks (LeNet)
    • 7  Modern Convnets
    • 7.1  AlexNet and Learned Image Representations
    • 7.2  Blocks, Bottlenecks, and Branches: VGG, NiN, GoogLeNet
    • 7.3  Normalization Layers
    • 7.4  Residual Networks: ResNet, ResNeXt, and DenseNet
    • 7.5  Efficient Convnets
    • 7.6  Modern Training Recipes for Convnets
    • 7.7  ConvNeXt: A ConvNet for the 2020s
    • 7.8  Convolutional Network Design Spaces
    • 8  Sequence Models
    • 8.1  Working with Sequences
    • 8.2  From Text to Tokens
    • 8.3  Language Models
    • 8.4  Recurrent Neural Networks
    • 8.5  Implementing RNNs
    • 8.6  Backpropagation Through Time
    • 8.7  Decoding and Generation
  • Advanced
    • 9  Optimization Algorithms
    • 9.1  Landscapes
    • 9.2  Gradient Descent
    • 9.3  Stochastic and Minibatch Gradient Descent
    • 9.4  Momentum
    • 9.5  Adam and AdamW
    • 9.6  Schedules
    • 9.7  Muon
    • 9.8  Batch Size
    • 9.9  Scaling Up
    • 9.10  Practice
    • 9.11  Further Reading
    • 10  Attention
    • 10.1  Queries, Keys, and Values
    • 10.2  Attention Scoring and Masking
    • 10.3  Multi-Head and Cross-Attention
    • 10.4  Positional Information
    • 10.5  The Cost of Attention
    • 10.6  Attention Circuits
    • 10.7  Further Reading
    • 11  Transformers
    • 11.1  The Transformer Block
    • 11.2  A GPT from Scratch
    • 11.3  Generation and the KV Cache
    • 11.4  Encoders, Decoders, and Cross-Attention
    • 11.5  Vision Transformer
    • 11.6  Mixture of Experts
    • 11.7  Scaling Laws
    • 11.8  Further Reading
    • 12  State Space Models
    • 12.1  Gated Recurrent Networks
    • 12.2  Linear Recurrences and State Space Models
    • 12.3  Selective State Space Models
    • 12.4  Matrix-State Recurrences
    • 12.5  The Delta Rule
    • 12.6  Hybrid Architectures
    • 12.7  Further Reading
    • 13  Computational Performance
    • 13.1  The Performance Model
    • 13.2  Hardware
    • 13.3  Compute Graphs and Compilation
    • 13.4  Memory and Precision
    • 13.5  Multi-GPU from First Principles
    • 13.6  Multi-GPU in Practice
    • 13.7  Case Study: Optimizing a Transformer
    • 13.8  Further Reading
    • 14  Reinforcement Learning
    • 14.1  Markov Decision Processes
    • 14.2  Dynamic Programming
    • 14.3  Temporal-Difference Learning
    • 14.4  Exploration
    • 14.5  Learning from Demonstrations
    • 14.6  Policy Gradient
    • 14.7  Baselines and Variance Reduction
    • 14.8  Function Approximation in Reinforcement Learning
    • 15  Deep Reinforcement Learning
    • 15.1  Actor-Critic Methods and Multi-Step Returns
    • 15.2  Trust Regions and Proximal Policy Optimization
    • 15.3  KL-Regularized Policy Optimization
    • 15.4  Deep Q-Networks
    • 15.5  Soft Actor-Critic
    • 15.6  Learned Models and Planning
    • 15.7  Offline Reinforcement Learning
    • 15.8  Reinforcement Learning for Sequence Generation
    • 15.9  Further Reading
    • 16  Generative Adversarial Networks
    • 16.1  Generative Adversarial Networks
    • 16.2  Adversarial Objectives and Divergences
    • 16.3  Relativistic Objectives
    • 16.4  Gradient Penalties and Convergence
    • 16.5  Adversarial Image Generation
    • 16.6  Conditional Generation
    • 16.7  Adversarial Losses Beyond GANs
    • 16.8  Further Reading
    • 17  Diffusion Models
    • 17.1  Denoising and the Score
    • 17.2  Gaussian Paths: Diffusion and Flow Matching
    • 17.3  Diffusion for Images
    • 17.4  Samplers, Inversion and Editing
    • 17.5  Likelihood, Weighting and the Design Space
    • 17.6  Latent Diffusion and Transformers
    • 17.7  Few-Step Generation
    • 17.8  Discrete Diffusion
    • 17.9  Further Reading
  • Language Models
    • 18  Working with Pretrained Language Models
    • 18.1  Pretrained Models with Hugging Face
    • 18.2  A Released Checkpoint in the Book’s Own Code
    • 18.3  Prompting and In-Context Learning
    • 18.4  Scoring Language Models
    • 18.5  Evaluation Suites, Judges and Error Bars
    • 18.6  Interpretability
    • 18.7  Models behind an API
    • 19  Encoders, Embeddings and Retrieval
    • 19.1  Word Embeddings
    • 19.2  Pretrained Encoders
    • 19.3  Text Embeddings from Contrastive Training
    • 19.4  Sparse, Dense and Approximate Retrieval
    • 19.5  Retrieval-Augmented Generation
    • 19.6  Further Reading
    • 20  Data for Language Models
    • 20.1  Document Extraction from Web Crawls
    • 20.2  Quality Filtering
    • 20.3  Deduplication and Decontamination
    • 20.4  Data Mixtures
    • 20.5  Synthetic and Rephrased Data
    • 20.6  Tokenizers at Scale
    • 21  Pretraining
    • 21.1  The Pretraining Data Path
    • 21.2  The Reference Pretraining Run
    • 21.3  Low-Precision Training
    • 21.4  Continued Pretraining and Mid-Training
    • 21.5  Long-Context Training
    • 21.6  Training Budgets beyond the Compute Optimum
    • 22  Hardware for Training and Inference
    • 22.1  Accelerator Design
    • 22.2  Kernels, Tiles and Fusion
    • 22.3  Training, Prefill and Decode Workloads
    • 22.4  Memory and Storage Tiers
    • 22.5  Data Paths inside a Server
    • 22.6  Scale-Up Domains and Scale-Out Networks
    • 22.7  Collective Communication at Scale
    • 22.8  Energy, Power and Cost
    • 23  Parallelism Beyond One Node
    • 23.1  Multi-Node Jobs and Hang Diagnosis
    • 23.2  Sharded Data Parallelism at Scale
    • 23.3  Tensor and Sequence Parallelism
    • 23.4  Pipeline Parallelism
    • 23.5  Context Parallelism
    • 23.6  Expert Parallelism
    • 23.7  Composed Parallelism and Topology
    • 23.8  Profiling and Performance Debugging of Distributed Runs
    • 23.9  Checkpoints at Scale
    • 23.10  Failures, Elasticity and Goodput
    • 24  Fine-Tuning
    • 24.1  Full Fine-Tuning
    • 24.2  Supervised Instruction Tuning
    • 24.3  Instruction Data
    • 24.4  Low-Rank Adaptation
    • 24.5  Quantized Fine-Tuning
    • 24.6  Fine-Tuning at Scale and Toolchains
    • 24.7  Merging and Retaining Capabilities
    • 25  Preference Optimization and Reinforcement Learning
    • 25.1  Reward Models
    • 25.2  RLHF with PPO at Language-Model Scale
    • 25.3  Direct Preference Optimization and Its Variants
    • 25.4  RL with Verifiable Rewards
    • 25.5  RL Training Systems
    • 25.6  Reward Overoptimization
    • 25.7  Safety Evaluation and Red-Teaming
    • 25.8  Further Reading
    • 26  Distillation and Reasoning
    • 26.1  Knowledge Distillation
    • 26.2  On-Policy Distillation
    • 26.3  Training Reasoning Models
    • 26.4  Verifiers and Process Supervision
    • 26.5  Parallel Test-Time Compute
    • 26.6  Sequential and Adaptive Test-Time Compute
    • 27  Agents and Tool Use
    • 27.1  Tool Calling
    • 27.2  Structured Outputs and Constrained Decoding
    • 27.3  Agent Loops and Harnesses
    • 27.4  Training Agents with Reinforcement Learning
    • 27.5  Evaluating and Securing Agents
    • 28  Model Compression
    • 28.1  Quantization for Inference
    • 28.2  Activation Outliers and Equivalent Rescaling
    • 28.3  Reconstruction-Based Quantization
    • 28.4  Rotations and Incoherence
    • 28.5  Quantization-Aware Training and Native Low-Bit Formats
    • 28.6  Pruning and Sparsity
    • 28.7  Further Reading
    • 29  Efficient Inference
    • 29.1  A Fast Decoder on One GPU
    • 29.2  Decode Attention Kernels
    • 29.3  Deterministic and Batch-Invariant Inference
    • 29.4  Speculative Decoding
    • 29.5  Drafters and Multi-Token Prediction
    • 29.6  KV-Cache Quantization
    • 29.7  KV-Cache Eviction and Selective Reading
    • 29.8  Inference on CPUs and Devices
    • 30  Serving Systems
    • 30.1  Workloads and Service Objectives
    • 30.2  Continuous Batching and Chunked Prefill
    • 30.3  Paged KV Memory
    • 30.4  Prefix Caching and Shared-Prefix Workloads
    • 30.5  Scheduling under Overload
    • 30.6  KV-Cache Offload, Stores and Prefix-Aware Routing
    • 30.7  Tensor and Expert Parallelism for Serving
    • 30.8  Prefill and Decode Disaggregation
    • 30.9  Serving Many Adapters
    • 31  Advanced Architectures
    • 31.1  Architecture Configurations
    • 31.2  Mixture-of-Experts Design at Scale
    • 31.3  Latent Attention and Cross-Layer KV Sharing
    • 31.4  Softmax Attention Refinements
    • 31.5  Learned Sparse Attention
    • 31.6  Hybrid Models at Scale
    • 31.7  The Residual Stream across Depth
    • 31.8  Further Reading
  • Image Models
    • 32  Computer Vision
    • 32.1  Image Augmentation
    • 32.2  Fine-Tuning
    • 32.3  Object Detection and Bounding Boxes
    • 32.4  Anchor Boxes
    • 32.5  Multiscale Object Detection
    • 32.6  The Object Detection Dataset
    • 32.7  Single Shot Multibox Detection
    • 32.8  Region-based CNNs (R-CNNs)
    • 32.9  Semantic Segmentation and the Dataset
    • 32.10  Transposed Convolution
    • 32.11  Fully Convolutional Networks
    • 32.12  Neural Style Transfer
    • 32.13  Image Classification (CIFAR-10) on Kaggle
    • 32.14  Dog Breed Identification (ImageNet Dogs) on Kaggle
  • Attic
    • 33  Gaussian Processes
    • 33.1  Introduction to Gaussian Processes
    • 33.2  Gaussian Process Priors
    • 33.3  Gaussian Process Inference
    • 34  Hyperparameter Optimization
    • 34.1  What Is Hyperparameter Optimization?
    • 34.2  Hyperparameter Optimization API
    • 34.3  Asynchronous Random Search
    • 34.4  Multi-Fidelity Hyperparameter Optimization
    • 34.5  Asynchronous Successive Halving
    • 35  Recommender Systems
    • 35.1  Overview of Recommender Systems
    • 35.2  The MovieLens Dataset
    • 35.3  Matrix Factorization
    • 35.4  AutoRec: Rating Prediction with Autoencoders
    • 35.5  Personalized Ranking for Recommender Systems
    • 35.6  Neural Collaborative Filtering for Personalized Ranking
    • 35.7  Sequence-Aware Recommender Systems
    • 35.8  Feature-Rich Recommender Systems
    • 35.9  Factorization Machines
    • 35.10  Deep Factorization Machines
    • 36  Natural Language Processing: Pretraining
    • 36.1  Encoder-Decoder Models for Sequence Transduction
    • 36.2  Word Embedding (word2vec)
    • 36.3  Approximate Training
    • 36.4  The Dataset for Pretraining Word Embeddings
    • 36.5  Pretraining word2vec
    • 36.6  Word Embedding with Global Vectors (GloVe)
    • 36.7  Subword Embedding
    • 36.8  Word Similarity and Analogy
    • 36.9  Bidirectional Encoder Representations from Transformers (BERT)
    • 36.10  The Dataset for Pretraining BERT
    • 36.11  Pretraining BERT
    • 37  Natural Language Processing: Applications
    • 37.1  Sentiment Analysis and the Dataset
    • 37.2  Sentiment Analysis: Using Recurrent Neural Networks
    • 37.3  Sentiment Analysis: Using Convolutional Neural Networks
    • 37.4  Natural Language Inference and the Dataset
    • 37.5  Natural Language Inference: Using Attention
    • 37.6  Fine-Tuning BERT for Sequence-Level and Token-Level Applications
    • 37.7  Natural Language Inference: Fine-Tuning BERT
  • Mathematics for Deep Learning
    • 38  Linear Algebra
    • 38.1  Vectors, Angles, and Projections
    • 38.2  Matrices as Linear Maps
    • 38.3  Eigendecompositions
    • 38.4  Singular Value Decomposition and Low-Rank Approximation
    • 38.5  Further Reading
    • 39  Calculus and Automatic Differentiation
    • 39.1  Single Variable Calculus
    • 39.2  Multivariable Calculus
    • 39.3  Matrix Calculus
    • 39.4  Automatic Differentiation
    • 39.5  Integral Calculus
    • 39.6  Further Reading
    • 40  Optimization
    • 40.1  Gradient Descent and Curvature
    • 40.2  Convexity
    • 40.3  Stochastic Gradient Methods
    • 40.4  Adaptive Methods
    • 40.5  Constrained Optimization
    • 40.6  Duality
    • 40.7  Numerical Stability and Conditioning
    • 40.8  Further Reading
    • 41  Probability and Statistical Learning
    • 41.1  Random Variables
    • 41.2  Distributions
    • 41.3  The Exponential Family
    • 41.4  Statistics
    • 41.5  Maximum Likelihood
    • 41.6  Bayesian Computation
    • 41.7  Concentration Inequalities
    • 41.8  Uniform Convergence and Generalization
    • 41.9  Naive Bayes
    • 41.10  Further Reading
    • 42  Information Theory and Divergences
    • 42.1  Entropy, Cross-Entropy, and KL Divergence
    • 42.2  Codes, Compression, and Perplexity
    • 42.3  Divergences and Distances Between Distributions
    • 42.4  Mutual Information
    • 42.5  Estimating Mutual Information
    • 42.6  Further Reading
    • 43  Dynamics: Differential Equations and Generative Flows
    • 43.1  Ordinary Differential Equations and Numerical Solvers
    • 43.2  Neural ODEs, Adjoints, and Continuous Flows
    • 43.3  Stochastic Differential Equations
    • 43.4  The Fokker–Planck Equation and Probability Flow
    • 43.5  Score Matching and Diffusion Models
    • 43.6  Flow Matching and Optimal Transport
    • 43.7  Further Reading
  • Tools for Deep Learning
    • 44  Tools for Deep Learning
    • 44.1  Notebooks
    • 44.2  Colab and Kaggle
    • 44.3  Cloud Computing
    • 44.4  Hardware
    • 44.5  Ecosystem
    • 44.6  Distributed Model Training
    • 44.7  Model Serving
    • 44.8  Contributor Guide
    • 44.9  Utility Functions and Classes
    • 44.10  The d2l API Reference
  • References

Dive into Deep Learning

Aston Zhang

Zachary C. Lipton

Mu Li

Alexander J. Smola

2026-11-10

Dive into Deep Learning

Interactive deep learning, with code, math, and discussions — implemented in PyTorch, JAX, TensorFlow, and MXNet.
By Aston Zhang, Zachary C. Lipton, Mu Li, and Alexander J. Smola · Adopted at 500+ universities in 70+ countries · Published by Cambridge University Press.

Get started Free PDF GitHub Discuss
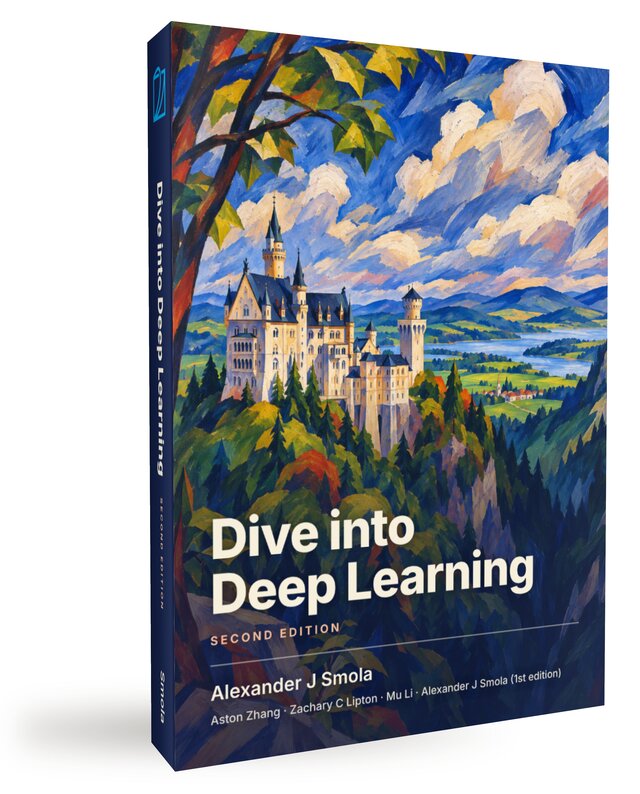
Dive into Deep Learning, Second Edition, book cover

One book, four frameworks

Every example runs end-to-end in your framework of choice. Switch tabs to see the same idea in idiomatic code for each.

  • PyTorch
  • JAX
  • TensorFlow
  • MXNet

What you get

{ }

Code you can run

Every concept ships with executable Jupyter notebooks. Tweak hyperparameters and see the effect immediately.

∑

Math grounded in intuition

Derivations stay close to the code. Equations, figures, and prose are interwoven, not relegated to appendices.

↔

Truly multi-framework

The same chapter, the same explanations, in PyTorch, JAX, TensorFlow, and MXNet. Pick your framework, keep the book.

☁

Runs anywhere

Local Jupyter, Google Colab, Amazon SageMaker Studio Lab, or your own GPU box. No paywalls, no setup hurdles.

🎓

Classroom-tested

Used as a primary or supplementary text at 500+ universities. Slide decks, exercises, and a discussion forum included.

∞

Always free, always evolving

The book is fully open-source. New chapters and corrections land continuously, in step with the field.

Authors

Aston Zhang Aston Zhang AWS
Zachary C. Lipton Zachary C. Lipton Carnegie Mellon University
Mu Li Mu Li Boson AI · AWS
Alexander J. Smola Alexander J. Smola Boson AI · CMU

Chapter contributors

Specialist authors who led the writing of individual chapters in the second volume.

Reinforcement Learning

Pratik Chaudhari Pratik Chaudhari UPenn · Amazon
Rasool Fakoor Rasool Fakoor Amazon
Kavosh Asadi Kavosh Asadi Amazon

Gaussian Processes

Andrew Gordon Wilson Andrew Gordon Wilson NYU · Amazon

Hyperparameter Optimization

Aaron Klein Aaron Klein Amazon
Matthias Seeger Matthias Seeger Amazon
Cedric Archambeau Cedric Archambeau Amazon

Recommender Systems

Shuai Zhang Shuai Zhang Amazon
Yi Tay Yi Tay Google

Mathematics for Deep Learning

Brent Werness Brent Werness Amazon
Rachel Hu Rachel Hu Amazon

Framework adaptation leads

Driving the per-framework code: porting every example to PyTorch, JAX, and TensorFlow.

Anirudh Dagar Anirudh Dagar PyTorch & JAX · Amazon
Yuan Tang Yuan Tang TensorFlow · Akuity

Adopted at universities worldwide

500+universities in 70+ countries teach with Dive into Deep Learning.
Abasyn University Islamabad Campus AGH University of Krakow Ain Shams University Alexandria University Amity University Amrita Vishwa Vidyapeetham Andhra University Anna University Ateneo de Naga University Australian Catholic University Australian National University Autonomous University of Barcelona Autonomous University of Madrid Bar Ilan University Barnard College Beijing Institute of Mathematical Sciences and Applications Beykoz University Birla Institute of Technology and Science Pilani BML Munjal University Boston College Boston University Brac University Brandeis University Brown University Budapest University of Technology and Economics Bursa Uludag University Cairo University Cankaya University Carnegie Mellon University Carnegie Mellon University Africa Charles University Chennai Mathematical Institute China Ocean University Chinese University of Hong Kong Chinese University of Hong Kong Shenzhen Chongqing University of Science and Technology Christ University Bengaluru Chulalongkorn University CINVESTAV City University of Hong Kong Cochin University of Science and Technology College of Engineering Pune Colorado State University Columbia University Concordia University Cornell University CUNY Graduate Center Cyprus Institute Dalian University of Technology Dayananda Sagar University Deakin University DePaul University Diponegoro University Duke University Durban University of Technology East China Normal University Eastern Mediterranean University Ecole Nationale Superieure dInformatique Emory University Eötvös Loránd University (ELTE), Budapest EPFL Escuela Politecnica Nacional Escuela Superior Politecnica del Litoral Ewha Womans University Federal University Lokoja Fenerbahce University Feng Chia University FPT University Free University of Berlin Fudan University Gayatri Vidya Parishad College of Engineering (Autonomous) Gazi Universitesi George Mason University Georgetown University Georgia Institute of Technology Goa University Golden Gate University Great Lakes Institute of Management Guangdong University of Technology Gwangju Institute of Science and Technology Habib University Hamad Bin Khalifa University Hangzhou Dianzi University Hankuk University of Foreign Studies Hanoi University of Science and Technology Harare Institute of Technology Harbin Institute of Technology Harokopio University Harvard University Hasso Plattner Institut Hebrew University of Jerusalem Heilongjiang University of Science and Technology Heinrich Heine Universitat Dusseldorf Heriot-Watt University Hertie School Hiroshima University Ho Chi Minh City University of Foreign Languages and Information Technology Ho Chi Minh City University of Technology Hochschule Bremen Hochschule fur Technik und Wirtschaft Hong Kong Baptist University Hong Kong Polytechnic University Hong Kong University of Science and Technology Huazhong University of Science and Technology Humboldt University of Berlin Imperial College London IMT Mines Ales Indian Institute of Information Technology Lucknow Indian Institute of Information Technology Una Indian Institute of Science Bangalore Indian Institute of Technology Bombay Indian Institute of Technology Delhi Indian Institute of Technology Gandhinagar Indian Institute of Technology Guwahati Indian Institute of Technology Hyderabad Indian Institute of Technology Jodhpur Indian Institute of Technology Kanpur Indian Institute of Technology Kharagpur Indian Institute of Technology Madras Indian Institute of Technology Mandi Indian Institute of Technology Patna Indian Institute of Technology Ropar Indian Institute of Technology Tirupati Indira Gandhi National Open University Indraprastha Institute of Information Technology, Delhi Information Technology University Lahore Institut catholique d'arts et metiers (ICAM) Institut de recherche en informatique de Toulouse Institut Superieur d'Informatique et des Techniques de Communication Institut Superieur De L'electronique Et Du Numerique Institut Teknologi Bandung Instituto Politécnico Nacional Instituto Tecnologico Autonomo de Mexico Instituto Tecnologico de Buenos Aires International Institute of Information Technology, Hyderabad Islamic University of Medina Istanbul Atlas University Istanbul Teknik Universitesi Istinye University IT Universitetet i Kobenhavn Jeonbuk National University Johns Hopkins University Kansas State University Keio University Kennesaw State University King Abdullah University of Science and Technology King Fahd University of Petroleum and Minerals King Faisal University Kongu Engineering College Korea Aerospace University KPR Institute of Engineering and Technology KU Leuven Kyung Hee University Kyungpook National University Lahore University of Management Sciences Lancaster University Leading University Leibniz Universitat Hannover Leuphana University of Luneburg Linköping University Liuzhou Institute of Technology LMU Munich London School of Economics and Political Science Lund University Make School Mar Baselios College of Engineering and Technology Marmara University Masaryk University Massachusetts Institute of Technology McGill University MEF University Menoufia University Michigan State University Middle East Technical University Middlebury College Milwaukee School of Engineering Minia University Mohammed V University in Rabat Monash University Multimedia University Murdoch University Nagoya University Nanchang Hangkong University Nanjing Normal University Zhongbei College Nanjing University Nanjing University of Finance and Economics National Central University National Cheng Kung University National Chengchi University National Chung Hsing University National Institute of Technical Teachers Training & Research National Institute of Technology, Warangal National Institute of Technology Delhi National Institute of Technology Kurukshetra National Institute of Technology Rourkela National Institute of Technology Tiruchirappalli National Sun Yat sen University National Taiwan University National Technical University of Athens National Technical University of Ukraine National United University National University of Sciences and Technology National University of Singapore Nazarbayev University New Jersey Institute of Technology New York University Newman University Noida Institute of Engineering and Technology North Carolina State University North Ossetian State University Northeastern University Northwestern University Norwegian University of Science and Technology NRI Institute of Technology Ohio University Oita University Ontario Tech University Pakuan University Peking University Pennsylvania State University PES University Pohang University of Science and Technology Politecnico di Milano Pomona College Pontificia Universidad Catolica de Chile Pontificia Universidad Catolica del Peru Pontificia Universidade Catolica do Rio de Janeiro Portland State University Prasad V. Potluri Siddhartha Institute of Technology Princeton University Purdue University Quaid-i-Azam University Queen's University Queen Mary University of London Radboud Universiteit Rensselaer Polytechnic Institute Rikkyo University Rowan University Rutgers, The State University of New Jersey RV University Bengaluru Sabanci University San Jose State University Sant Longowal Institute of Engineering Technology Santa Clara University Sanya University Sapienza Universita di Roma Sardar Vallabhbhai National Institute of Technology, Surat Seoul National University Seoul National University of Science and Technology Shahid Beheshti University Shandong University Shanghai Jiao Tong University Shanghai University of Electric Power Shanghai University of Finance and Economics ShanghaiTech University Sharif University of Technology Shenzhen University Shiv Nadar University Shivaji University Kolhapur Simon Fraser University Singapore University of Technology and Design Skolkovo Institute of Science and Technology Sogang University Sookmyung Women's University Southern New Hampshire University Southern Utah University SRM Institute of Science and Technology St. Polten University of Applied Sciences Stanford University State University of New York at Binghamton Stellenbosch University Stevens Institute of Technology Stockholm University Stony Brook University Sungkyunkwan University Technical University of Darmstadt Technical University of Munich Technion   Israel Institute of Technology Technische Universitat Berlin Technische Universiteit Delft Tecnológico de Monterrey, Campus Guadalajara Tekirdag Namik Kemal Universitesi Texas A&M University Texas Christian University Thapar Institute of Engineering and Technology Tohoku University Trinity College Dublin Tsinghua University Tufts University Tunghai University Umea University United International University Universidad Carlos III de Madrid Universidad de Buenos Aires Universidad de Chile Universidad de Ibagué Universidad de Ingeniería y Tecnología Universidad de los Andes Universidad de Salamanca Universidad de Zaragoza Universidad del Norte Universidad Icesi Universidad Militar Nueva Granada Universidad Nacional Agraria La Molina Universidad Nacional Autonoma de Mexico Universidad Nacional de Colombia Sede Manizales Universidad Nacional de Tierra del Fuego Universidad Politécnica Salesiana, Cuenca Universidad Politecnica de Madrid Universidad Rafael Landívar Universidad Rey Juan Carlos Universidad San Francisco de Quito Universidad Tecnológica Nacional Universidad Tecnologica de Pereira Universidade Catolica de Brasilia Universidade de Coimbra Universidade Estadual de Campinas Universidade Federal de Goiás Universidade Federal de Minas Gerais Universidade Federal de Ouro Preto Universidade Federal de Pernambuco Universidade Federal de São Carlos Universidade Federal de Santa Catarina Universidade Federal de Viçosa Universidade Federal do Pampa Universidade Federal do Rio de Janeiro Universidade Federal do Rio Grande Universidade Lusófona Universidade NOVA de Lisboa Universidade Presbiteriana Mackenzie Universidade Tecnológica Federal do Paraná Università degli Studi di Pavia Universita Bocconi Universita degli Studi di Bari Aldo Moro Universita degli Studi di Brescia Universita degli Studi di Padova Università degli Studi di Roma Tor Vergata Università degli Studi di Bologna Universitas Andalas, Padang Universitas Indonesia Universitas Negeri Yogyakarta Universitas Udayana Universitat de Barcelona Universitat Heidelberg Universitat Politecnica de Catalunya Universitat Tubingen Universitatea Babes Bolyai Universitatea de Vest din Timisoara Universite Cote dAzur Universite de technologie de Compiegne Université Grenoble Alpes Universite Paris Saclay Universiteit Leiden Universiteit van Amsterdam University at Buffalo University College Dublin University of Arkansas University of Augsburg University of Aveiro University of Baghdad University of Bamberg University of Basel University of Bristol University of British Columbia University of Cagliari University of California, Berkeley University of California, Irvine University of California, Los Angeles University of California, San Diego University of California, Santa Barbara University of California, Santa Cruz University of Cambridge University of Canberra University of Catania University of Central Florida University of Chinese Academy of Sciences University of Cincinnati University of Colorado Denver University of Connecticut University of Copenhagen University of Delaware University of Edinburgh University of Florence University of Florida University of Ghana University of Granada University of Groningen University of Hamburg University of Hawaii at Manoa University of Hull University of Iceland University of Idaho University of Illinois at Chicago University of Illinois Urbana Champaign University of International Business and Economics University of Juba University of Jyväskylä University of Kentucky University of Klagenfurt University of Liege University of Lisbon University of Ljubljana University of Louisville University of Luxembourg University of Maryland University of Maryland Baltimore County University of Melbourne University of Michigan University of Milan Università degli Studi di Milano-Bicocca University of Minnesota, Twin Cities University of Moratuwa University of Mosul University of Nebraska-Lincoln University of Nevada, Reno University of New Hampshire University of New South Wales University of Newcastle University of North Carolina at Chapel Hill University of North Carolina at Charlotte University of North Texas University of Northern Philippines University of Nottingham University of Oklahoma University of Oslo University of Patras University of Pennsylvania University of Pittsburgh University of Rhode Island University of Rochester University of Sao Paulo University of Science and Technology of China University of South Australia University of Southern California University of Southern Maine University of St Andrews University of Sydney University of Szeged University of Technology Sydney University of Tehran University of Texas at Arlington University of Texas at Austin University of Texas at Dallas University of Tokyo University of Toronto University of Virginia University of Warsaw University of Washington University of Waterloo University of Wisconsin–Madison Univerzita Komenskeho v Bratislave Van Yuzuncu Yil University Vardhaman College of Engineering Vardhman Mahaveer Open University Vietnam National University, Hanoi Vietnamese German University Virginia Commonwealth University Virginia Tech Visvesvaraya National Institute of Technology Nagpur VIT (Vellore Institute of Technology), Vellore VNU-HCM University of Science Wageningen University West Virginia University Western University Xavier University Bhubaneswar Xi'an Jiaotong Liverpool University Xiamen University Yale University Yeshiva University Yildiz Technical University Yonsei University Yunnan University Zhejiang University Zhengzhou Tourism College
Click a logo to see a course at that institution adopting the book.

What people are saying

In a way that strikes the perfect balance between hands-on learning and mathematical rigor, this book is the most accessible and resourceful guide to deep learning we currently have.

Course adopter, R1 university

The notebooks make it easy to get students from zero to a working model in a single lecture. The math is there when you want it and stays out of the way when you don't.

Instructor, graduate ML course

I switched from PyTorch to JAX mid-semester and didn't have to switch textbooks. That alone is unheard of.

Researcher, industry lab

Cite the book

@book{zhang2023dive,
  title     = {Dive into Deep Learning},
  author    = {Zhang, Aston and Lipton, Zachary C. and Li, Mu and Smola, Alexander J.},
  publisher = {Cambridge University Press},
  note      = {\url{https://D2L.ai}},
  year      = {2023}
}

Resources

Read the bookStart with the preface PDF (PyTorch)Single-file download Source on GitHubNotebooks & library CoursesSlides & videos Discussion forumPer-chapter Q&A Chinese edition中文版

Global university adoption

World map showing universities teaching Dive into Deep Learning
Preface
 
Cookie Preferences