%matplotlib inline
import time
from d2l import torch as d2l
import torch
import torchvision
from torchvision import transforms

d2l.use_svg_display()3.2 The Image Classification Dataset
MNIST (LeCun et al. 1998) is a widely used image-classification benchmark with 70,000 handwritten-digit images (\(28 \times 28\) pixels, 10 classes). Many simple models now achieve high accuracy on it, which makes differences among model classes less visible.
We therefore use Fashion-MNIST (Xiao et al. 2017), a 2017 replacement with the same structure: 60,000 training and 10,000 test images, each containing \(28 \times 28\) grayscale pixels from one of 10 clothing categories. These categories provide a more discriminating comparison of the models developed in this chapter. ImageNet (Deng et al. 2009) supports larger-scale experiments with 1.2 million images and 1000 classes, but Fashion-MNIST keeps the examples interactive.
%matplotlib inline
import time
from d2l import tensorflow as d2l
import tensorflow as tf

d2l.use_svg_display()%matplotlib inline
from d2l import jax as d2l
import jax
from jax import numpy as jnp
import numpy as np
import time
import tensorflow as tf
d2l.use_svg_display()%matplotlib inline
import time
from d2l import mxnet as d2l
from mxnet import gluon, npx
from mxnet.gluon.data.vision import transforms
npx.set_np()
d2l.use_svg_display()3.2.1 Loading the Dataset
The library provides a preprocessed version of Fashion-MNIST that we can download and read into memory.
class FashionMNIST(d2l.DataModule):
    """The Fashion-MNIST dataset."""
    def __init__(self, batch_size=64, resize=(28, 28)):
        super().__init__()
        self.save_hyperparameters()
        trans = transforms.Compose([transforms.Resize(resize),
                                    transforms.ToTensor()])
        self.train = torchvision.datasets.FashionMNIST(
            root=self.root, train=True, transform=trans, download=True)
        self.val = torchvision.datasets.FashionMNIST(
            root=self.root, train=False, transform=trans, download=True)
class FashionMNIST(d2l.DataModule):
"""The Fashion-MNIST dataset."""
def __init__(self, batch_size=64, resize=(28, 28)):
super().__init__()
self.save_hyperparameters()
self.train, self.val = tf.keras.datasets.fashion_mnist.load_data()class FashionMNIST(d2l.DataModule):
"""The Fashion-MNIST dataset."""
def __init__(self, batch_size=64, resize=(28, 28)):
super().__init__()
self.save_hyperparameters()
self.train, self.val = tf.keras.datasets.fashion_mnist.load_data()class FashionMNIST(d2l.DataModule):
"""The Fashion-MNIST dataset."""
def __init__(self, batch_size=64, resize=(28, 28)):
super().__init__()
self.save_hyperparameters()
trans = transforms.Compose([transforms.Resize(resize),
transforms.ToTensor()])
self.train = gluon.data.vision.FashionMNIST(
train=True).transform_first(trans)
self.val = gluon.data.vision.FashionMNIST(
train=False).transform_first(trans)Fashion-MNIST consists of images from 10 categories, each represented by 6000 images in the training dataset and by 1000 in the test dataset. A test dataset is used for evaluating model performance (it must not be used for training). Consequently the training set and the test set contain 60,000 and 10,000 images, respectively.
data = FashionMNIST(resize=(32, 32))
len(data.train), len(data.val)
(60000, 10000)data = FashionMNIST(resize=(32, 32))
len(data.train[0]), len(data.val[0])(60000, 10000)data = FashionMNIST(resize=(32, 32))
len(data.train[0]), len(data.val[0])(60000, 10000)data = FashionMNIST(resize=(32, 32))
len(data.train), len(data.val)(60000, 10000)Fashion-MNIST images are natively \(28\times28\). We use resize=(32, 32) to match the spatial dimensions used by later convolution examples; interpolation changes the pixels and increases per-image storage and compute, but not the labels. Each image is delivered as a single-channel tensor of spatial size \(32 \times 32\). One subtlety matters here: where the channel axis lives. There are two conventions, channel-first \(c \times h \times w\) and channel-last \(h \times w \times c\). The data pipeline produces the appropriate layout, which we confirm after constructing the loader. Here \(c = 1\) because the images are grayscale; most photographs have \(c = 3\).
The categories of Fashion-MNIST have human-understandable names. The following convenience method converts between numeric labels and their names.
@d2l.add_to_class(FashionMNIST)
def text_labels(self, indices):
    """Return text labels."""
    labels = ['t-shirt', 'trouser', 'pullover', 'dress', 'coat',
              'sandal', 'shirt', 'sneaker', 'bag', 'ankle boot']
    return [labels[int(i)] for i in indices]
3.2.2 Reading a Minibatch
We use the built-in data iterator to read the training and test sets. Recall that at each iteration, a data iterator reads a minibatch of data with size batch_size. We also randomly shuffle the examples for the training data iterator.
@d2l.add_to_class(FashionMNIST)
def get_dataloader(self, train):
    data = self.train if train else self.val
    return torch.utils.data.DataLoader(data, self.batch_size, shuffle=train,
num_workers=self.num_workers)@d2l.add_to_class(FashionMNIST)
def get_dataloader(self, train):
data = self.train if train else self.val
process = lambda X, y: (tf.expand_dims(X, axis=3) / 255,
tf.cast(y, dtype='int32'))
resize_fn = lambda X, y: (tf.image.resize_with_pad(X, *self.resize), y)
shuffle_buf = len(data[0]) if train else 1
# `drop_remainder=train` keeps every training minibatch the same
# shape so Keras `model.fit` / a `@tf.function`'d train-step compile
# once and stop retracing for the smaller last batch (a major
# speedup for HPO loops where a fresh model is fit per trial).
return tf.data.Dataset.from_tensor_slices(process(*data)).shuffle(
shuffle_buf).batch(self.batch_size,
drop_remainder=train).map(resize_fn)@d2l.add_to_class(FashionMNIST)
def get_dataloader(self, train):
data = self.train if train else self.val
process = lambda X, y: (tf.expand_dims(X, axis=3) / 255,
tf.cast(y, dtype='int32'))
resize_fn = lambda X, y: (tf.image.resize_with_pad(X, *self.resize), y)
shuffle_buf = len(data[0]) if train else 1
# `drop_remainder=train` keeps every training minibatch the same
# shape, so JAX does not retrace the `@jax.jit`'d step function for
# a smaller last batch.
dataset = (tf.data.Dataset.from_tensor_slices(process(*data)).shuffle(
shuffle_buf).batch(self.batch_size, drop_remainder=train).map(
resize_fn))
return d2l.TensorFlowDataLoader(dataset)@d2l.add_to_class(FashionMNIST)
def get_dataloader(self, train):
data = self.train if train else self.val
return gluon.data.DataLoader(data, self.batch_size, shuffle=train,
num_workers=self.num_workers)We read one image to confirm the location of the channel axis.
X, y = next(iter(data.train_dataloader()))
X[0].shape  # channel-first: (channels, height, width)
torch.Size([1, 32, 32])X, y = next(iter(data.train_dataloader()))
X[0].shape # channel-last: (height, width, channels)TensorShape([32, 32, 1])X, y = next(iter(data.train_dataloader()))
X[0].shape # channel-last: (height, width, channels)(32, 32, 1)X, y = next(iter(data.train_dataloader()))
X[0].shape # channel-first: (channels, height, width)(1, 32, 32)Here is the same batch again, now at batch granularity: the first axis is the batch dimension (64 images per step by default), followed by the per-image shape we just confirmed, and the labels arrive as a matching vector of 64 integers.
X, y = next(iter(data.train_dataloader()))
print(X.shape, X.dtype, y.shape, y.dtype)torch.Size([64, 1, 32, 32]) torch.float32 torch.Size([64]) torch.int64(64, 32, 32, 1) <dtype: 'float32'> (64,) <dtype: 'int32'>(64, 32, 32, 1) float32 (64,) int32(64, 1, 32, 32) float32 (64,) int32We time one full pass through the training set as a local loader check. The result depends on storage, worker count, framework, and hardware; it tells us whether loading is a bottleneck only for this run. If loading is slower than training on a target system, prefetching or additional loader workers may help.
tic = time.time()
for X, y in data.train_dataloader():
    continue
f'{time.time() - tic:.2f} sec''2.27 sec''0.77 sec''0.75 sec''3.03 sec'3.2.3 Visualization
We will often be using the Fashion-MNIST dataset. The d2l library provides a convenience function show_images that lays out a list of images in a grid with optional per-image titles.
We visualize a minibatch before training. This check can reveal mislabeled examples, unexpected transformations, or shape errors early. Here are the images and their corresponding labels (in text) for the first few examples in the training dataset.
@d2l.add_to_class(FashionMNIST)
def visualize(self, batch, nrows=1, ncols=8, labels=None):
    X, y = batch
    if not labels:
        labels = self.text_labels(y)
    d2l.show_images(X.squeeze(1), nrows, ncols, titles=labels)
batch = next(iter(data.val_dataloader()))
data.visualize(batch)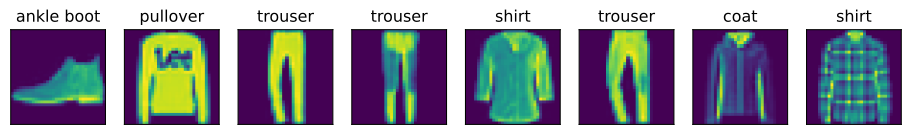
@d2l.add_to_class(FashionMNIST)
def visualize(self, batch, nrows=1, ncols=8, labels=None):
    X, y = batch
    if not labels:
        labels = self.text_labels(y)
    d2l.show_images(tf.squeeze(X), nrows, ncols, titles=labels)
batch = next(iter(data.val_dataloader()))
data.visualize(batch)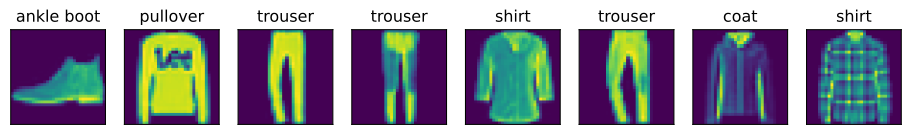
@d2l.add_to_class(FashionMNIST)
def visualize(self, batch, nrows=1, ncols=8, labels=None):
    X, y = batch
    if not labels:
        labels = self.text_labels(y)
    d2l.show_images(jnp.squeeze(X), nrows, ncols, titles=labels)

batch = next(iter(data.val_dataloader()))
data.visualize(batch)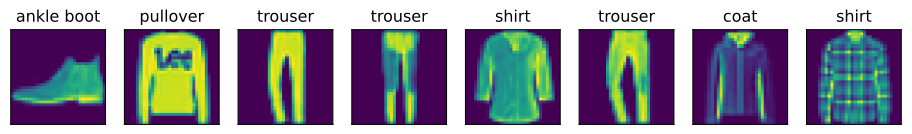
@d2l.add_to_class(FashionMNIST)
def visualize(self, batch, nrows=1, ncols=8, labels=None):
    X, y = batch
    if not labels:
        labels = self.text_labels(y)
    d2l.show_images(X.squeeze(1), nrows, ncols, titles=labels)
batch = next(iter(data.val_dataloader()))
data.visualize(batch)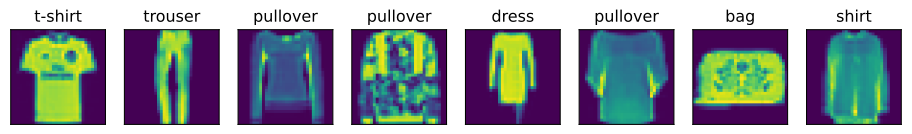
We are now ready to work with the Fashion-MNIST dataset in the sections that follow.
3.2.4 Summary
Fashion-MNIST contains grayscale apparel images from 10 categories. A batch has a batch axis, two spatial axes, and one channel axis: PyTorch and MXNet use \((n,c,h,w)\), while TensorFlow and JAX use \((n,h,w,c)\). The visualization uses false color, but the underlying data have one grayscale channel. Loader throughput must be measured together with model computation on the target system; it is not guaranteed to be faster than training.
3.2.5 Exercises
- [code] Throughput versus batch size. Time one full pass of
train_dataloaderover the training set forFashionMNISTconstructed withbatch_sizeof 1, 16, 64, 256, and 1024. Plot throughput (images per second) againstbatch_sizeand explain the shape of the curve in terms of per-batch overhead and per-image work. - Channel layout. The PyTorch and MXNet loaders deliver images channel-first, \((c, h, w)\), while the TensorFlow and JAX loaders deliver them channel-last, \((h, w, c)\). Read the
FashionMNISTconstructor andget_dataloaderin all four frameworks. For each framework, identify the operation that determines where the channel axis ends up, and locate the exact place where the layouts diverge. - [code] Cost of resizing. The section resizes the native \(28 \times 28\) images to \(32 \times 32\). Compute the float32 storage per image at both resolutions, and time one pass of
train_dataloaderwithresize=(28, 28)and withresize=(32, 32). - [code] Upsampling and linear models. ● Treat the resizing from \(28 \times 28\) to \(32 \times 32\) as a linear map \(\mathbf{x}' = \mathbf{A}\mathbf{x}\) from the 784 original pixels to the 1024 resized ones, where the columns of \(\mathbf{A} \in \mathbb{R}^{1024 \times 784}\) are linearly independent.
- Show that softmax regression on \(\mathbf{x}'\) can represent exactly the classifiers that softmax regression on \(\mathbf{x}\) can.
- After Section 3.4, train
SoftmaxRegressionScratchat both resolutions, withnum_inputsset to the number of pixels per image. Compare the validation accuracies and explain any difference in light of the previous part.
- Shuffling and validation.
get_dataloaderreshuffles the training split every epoch and reads the validation split in the same order every epoch. Suppose the validation loader, with the defaultbatch_size=64, were reshuffled every epoch as well.- Explain whether the validation loss and accuracy, averaged over all 10,000 validation examples, would change.
Module.plotdraws one validation point per epoch, the unweighted mean of the per-batch values. Explain whether this point would change.- Explain whether the images that
visualizeshows for the first validation batch would change. - Explain why the training loader is shuffled nonetheless.
- [code] Worker ablation.
get_dataloaderpasses thenum_workersattribute, whichDataModulesets to 4 by default, totorch.utils.data.DataLoader. Fordata = FashionMNIST(), time one pass ofdata.train_dataloader()withdata.num_workersset to 0, 1, 2, 4, and 8, where 0 loads in the main process. State under what conditions increasingnum_workersstops helping.
- [code] Parallel loading. The
tf.datapipeline inget_dataloaderdoes not use thenum_workersattribute ofDataModule; its parallelism is set per stage. Time one pass oftrain_dataloaderas written, then withnum_parallel_calls=tf.data.AUTOTUNEin themapcall and a trailing.prefetch(tf.data.AUTOTUNE). State under what conditions additional parallelism stops helping.
- [code] Worker ablation.
get_dataloaderpasses thenum_workersattribute, whichDataModulesets to 4 by default, togluon.data.DataLoader. Fordata = FashionMNIST(), time one pass ofdata.train_dataloader()withdata.num_workersset to 0, 1, 2, 4, and 8, where 0 loads in the main process. State under what conditions increasingnum_workersstops helping.
- [extended] Loader or compute. ● Combine the two sweeps of problems 1 and 6 into a grid of batch sizes and loader-parallelism settings, and measure loader throughput in images per second at each point. After Section 3.4, measure the throughput of a full training step of
SoftmaxRegressionScratch(forward pass, loss, gradient, and parameter update) on a minibatch held in memory, at the same batch sizes. Draw a heatmap of the ratio of loader throughput to training throughput over the grid. Identify the region of the grid in which loading is the bottleneck, and state whether a crossover exists on your hardware.