pairs = jnp.stack(jnp.meshgrid(jnp.arange(K), jnp.arange(K), indexing='ij'),
                  -1).reshape(-1, 2)  # all 1024 pairs
patterns = jnp.array([[True, False], [False, True], [True, True]])

def exact_bound(model):  # the bound averaged over the true table, all steps and patterns
    total = 0.0
    for t in range(1, T + 1):
        weight = (alpha_bar[t - 1] - alpha_bar[t]) / (1 - alpha_bar[t])
        for masked in patterns:
            masked = jnp.broadcast_to(masked, pairs.shape)
            z = jnp.where(masked, MASK, pairs)
            logp = jax.nn.log_softmax(model(z, jnp.full((len(pairs),), t)), -1)
            logp = jnp.take_along_axis(logp, pairs[..., None], -1)[..., 0]
            n_masked = masked[0].sum()
            prob = (1 - alpha_bar[t]) ** n_masked * alpha_bar[t] ** (2 - n_masked)
            total += prob * weight * (table.flatten() * (-logp * masked).sum(1)).sum()
    return total

@nnx.jit
def masked_step(model, optimizer, x0, t, key):
    loss, grads = nnx.value_and_grad(
        lambda m: masked_loss(m, x0, t, key).mean())(model)
    optimizer.update(model, grads)
    return loss

model = MaskedMLP(rngs=nnx.Rngs(1))
schedule = optax.piecewise_constant_schedule(1e-3, {4000: 0.2})
optimizer = nnx.Optimizer(model, optax.adam(schedule), wrt=nnx.Param)
for step in range(6000):
    key, k1, k2, k3 = jax.random.split(key, 4)
    x0 = data[jax.random.randint(k1, (512,), 0, len(data))]
    t = jax.random.randint(k2, (512,), 1, T + 1)
    loss = masked_step(model, optimizer, x0, t, k3)
    if step % 2000 == 0:
        print(f'step {step:>4}: exact bound {exact_bound(model):.3f} nats')
print(f'final exact bound {exact_bound(model):.3f} nats; entropy {entropy:.3f} nats')Discrete Diffusion
Dive into Deep Learning · §17.11
Discrete diffusion
transition matrices · the absorbing kernel · a weighted cross-entropy · unmasking
Noise for Tokens: Transition Matrices
q(\mathbf{x}_t \mid \mathbf{x}_{t-1}) = \mathrm{Cat}(\mathbf{x}_t;\ \mathbf{x}_{t-1} Q_t),\qquad q(\mathbf{x}_t \mid \mathbf{x}_0) = \mathrm{Cat}(\mathbf{x}_t;\ \mathbf{x}_0 Q_1 \cdots Q_t)
- uniform kernel: resample with probability \beta_t, stationary law uniform;
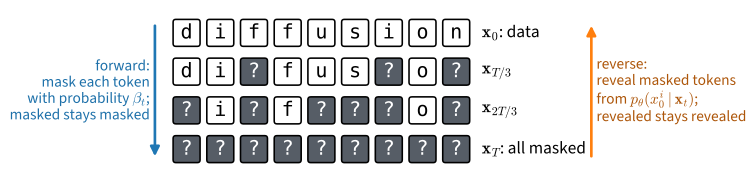
- absorbing kernel: move to [\textrm{M}] with probability \beta_t, masks stay;
- both collapse: \bar{Q}_t = \bar{\alpha}_t I + (1 - \bar{\alpha}_t) P with P^2 = P.
Forward Masks, Reverse Reveals
The Posterior Has Two Points
q(\mathbf{x}_{t-1} = \mathbf{x}_0 \mid \mathbf{x}_t = [\textrm{M}], \mathbf{x}_0) = \frac{\bar{\alpha}_{t-1} - \bar{\alpha}_t}{1 - \bar{\alpha}_t},\qquad q(\mathbf{x}_{t-1} = [\textrm{M}] \mid \cdots) = \frac{1 - \bar{\alpha}_{t-1}}{1 - \bar{\alpha}_t}
- an unmasked token stays; a masked one reverts or stays masked;
- the model: same two-point law, with p_{\boldsymbol{\theta}}(\mathbf{x}_0^i \mid \mathbf{x}_t) in place of \mathbf{x}_0.
The Bound Is a Weighted Cross-Entropy
L_{\textrm{VLB}} = \sum_{t=1}^{T} \frac{\bar{\alpha}_{t-1} - \bar{\alpha}_t}{1 - \bar{\alpha}_t}\; \mathbb{E}\Big[ \sum_{i \,:\, \mathbf{x}_t^i = [\textrm{M}]} -\log p_{\boldsymbol{\theta}}(\mathbf{x}_0^i \mid \mathbf{x}_t) \Big]
- the KL at a masked position is -w_t \log p_{\boldsymbol{\theta}}(\mathbf{x}_0^i \mid \mathbf{x}_t);
- linear schedule: w_t = 1/t, and every step carries the same expected weighted count of masks;
- in continuous time, with the masking level as the network’s input, the bound is invariant to the schedule.
The Quantized Mixture Has a Known Entropy
step    0: exact bound 6.876 nats
step 2000: exact bound 4.875 nats
step 4000: exact bound 4.872 nats
final exact bound 4.864 nats; entropy 4.840 nats
The bound averaged over the true table cannot fall below its entropy; the gap is model error plus looseness.
Fewer Steps, More Independence
def unmask(model, key, n, steps):
    z = jnp.full((n, 2), MASK)
    levels = [round(l) for l in jnp.linspace(T, 0, steps + 1).tolist()]
    for t, s in zip(levels[:-1], levels[1:]):
        key, k1, k2 = jax.random.split(key, 3)
        draw = jax.random.categorical(k1, model(z, jnp.full((n,), t)), axis=-1)
        reveal = (z == MASK) & (jax.random.uniform(k2, z.shape)
                                < (alpha_bar[s] - alpha_bar[t]) / (1 - alpha_bar[t]))
        z = jnp.where(reveal, draw, z)
    return z

samples = {}
print(f'{"steps":>5} {"TV to table":>12} {"predicted":>10} {"TV to product":>14}')
for steps in (32, 8, 2, 1):
    key, subkey = jax.random.split(key)
    samples[steps] = unmask(model, subkey, 20000, steps)
    h = histogram(samples[steps])
    print(f'{steps:>5} {tv(h, table):>12.3f} {tv(product, table) / steps:>10.3f} '
          f'{tv(h, product):>14.3f}')
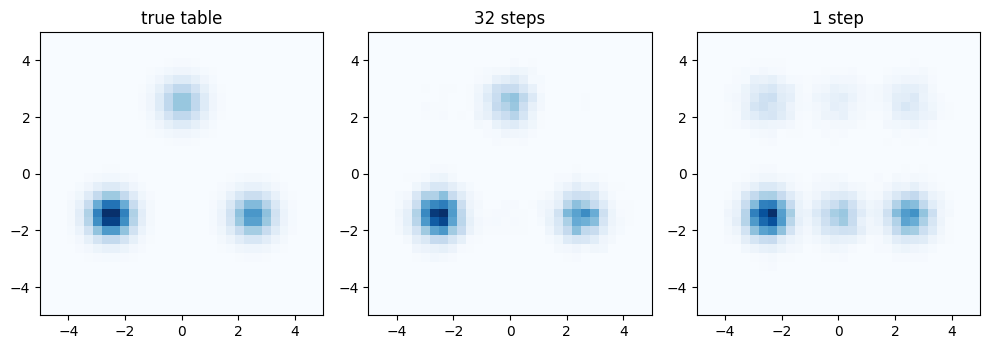
steps TV to table predicted TV to product
32 0.061 0.010 0.311
8 0.076 0.039 0.283
2 0.165 0.157 0.171
1 0.302 0.314 0.057Two tokens revealed in the same step are drawn independently: with S steps the sampler mixes in the product of the marginals with weight 1/S.
One Step Draws the Product
Binary Images by Unmasking
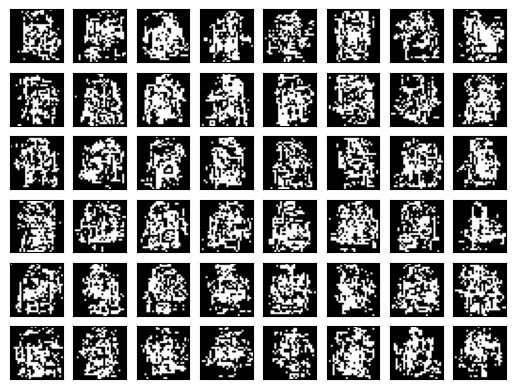
speckles: training images 0.0037, 100-step samples 0.0076, 4-step samples 0.0243The same U-Net, three input channels and two output channels; a hundred reveal steps, then four.
Recap
- Transition matrices replace Gaussian kernels; the bound is unchanged.
- Absorbing kernel: two-point posterior, weighted cross-entropy on masks.
- Unmasking trades steps for an independence error, measured exactly here.
- One step draws all tokens independently; one token per step is any-order autoregression.