Noise-Conditional Score Networks and Annealed Langevin Dynamics

Dive into Deep Learning · §17.6

Noise-conditional score networks and annealed Langevin dynamics
a ladder of noise levels · one network for all of them · sample coarse to fine

A Ladder of Noise Levels Removes the Trade-off
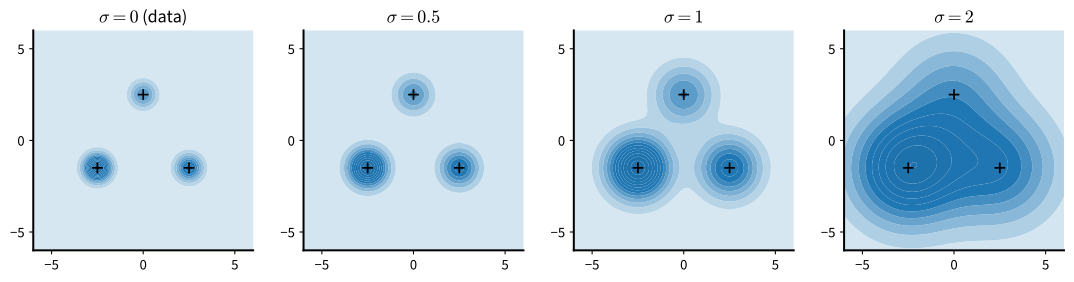
Coarse levels have no valleys and reliable scores wherever the noisy data reach; fine levels match the data. Use all of them, in order.

One Network, Conditioned on the Level

\mathcal{L}(\boldsymbol{\theta}) = \frac{1}{L} \sum_{i=1}^{L} \sigma_i^2\; \mathbb{E}\Big[ \tfrac{1}{2} \big\| \mathbf{s}_{\boldsymbol{\theta}}(\mathbf{x} + \sigma_i \boldsymbol{\epsilon}, \sigma_i) + \boldsymbol{\epsilon} / \sigma_i \big\|^2 \Big]

  • the \sigma^2 weight gives every level a term of comparable size;
  • with \mathbf{s}_{\boldsymbol{\theta}} = \mathbf{f}_{\boldsymbol{\theta}} / \sigma, the network predicts -\boldsymbol{\epsilon};
  • the fit is best at the coarse levels and worst at the finest.
print(f'{"sigma":>6} {"Fisher divergence":>18} {"0.5 E||score||^2":>17}')
for sigma in sigmas[::3]:
    key, subkey = jax.random.split(key)
    x_noisy = test + sigma * jax.random.normal(subkey, test.shape)
    true = mix.score(x_noisy, sigma=float(sigma))
    s = score(x_noisy, jnp.full((len(test),), sigma))
    print(f'{sigma:>6.3f} {0.5 * ((s - true) ** 2).sum(1).mean():>18.4f} '
          f'{0.5 * (true ** 2).sum(1).mean():>17.3f}')
 sigma  Fisher divergence  0.5 E||score||^2
 3.000             0.0017             0.076
 0.766             0.0296             1.122
 0.196             0.1071             3.430
 0.050             2.4424             3.950

Annealed Langevin Dynamics

\alpha_i = \epsilon\, \frac{\sigma_i^2}{\sigma_L^2}, \qquad \mathbf{x} \leftarrow \mathbf{x} + \frac{\alpha_i}{2}\, \mathbf{s}_{\boldsymbol{\theta}}(\mathbf{x}, \sigma_i) + \sqrt{\alpha_i}\, \boldsymbol{\xi}

For i = 1, \ldots, L, a fixed number of steps each, every level starting where the last one stopped. The step size tracks the score’s scale; the injected noise shrinks with the level.

The Ladder Recovers What One Level Could Not

@nnx.jit
def annealed_step(score, x, key, sigma, alpha):
    sigma_vec = jnp.full((len(x),), sigma)
    return (x + 0.5 * alpha * score(x, sigma_vec)
            + alpha ** 0.5 * jax.random.normal(key, x.shape))

def annealed_langevin(score, x, key, sigmas, steps_per_level=100, scale=0.1):
    """Langevin dynamics at each level of the ladder, coarse to fine."""
    for sigma in sigmas:
        alpha = scale * sigma ** 2  # alpha_i = eps * sigma_i^2 / sigma_L^2
        for _ in range(steps_per_level):
            key, subkey = jax.random.split(key)
            x = annealed_step(score, x, subkey, sigma, alpha)
    return x

def summarize(x):
    """Mode weights, within-mode spread, and the fraction of stray chains."""
    d2 = ((x[:, None, :] - mix.means[None]) ** 2).sum(-1)
    weights = [round(float(w), 3) for w in
               jnp.bincount(d2.argmin(1), length=3) / len(x)]
    nearest = d2.min(1)
    inside = nearest < (3 * mix.std) ** 2
    return (f'mode weights {weights}, spread {nearest[inside].mean():.2f}, '
            f'stray {1 - inside.mean():.3f}')

key, subkey = jax.random.split(key)
x_init = 3 * jax.random.normal(subkey, (2000, 2))
print(f'target (2000 samples of the mixture): {summarize(data)}')
for steps in (20, 100):
    key, subkey = jax.random.split(key)
    x = annealed_langevin(score, x_init, subkey, sigmas, steps_per_level=steps)
    print(f'annealed, {steps:>3d} steps per level: {summarize(x)}')
key, subkey = jax.random.split(key)
x_single = annealed_langevin(score, x_init, subkey, sigmas[-1:],
                             steps_per_level=1000)
print(f'finest level only, 1000 steps:  {summarize(x_single)}')
target (2000 samples of the mixture): mode weights [0.517, 0.296, 0.187], spread 0.46, stray 0.011
annealed,  20 steps per level: mode weights [0.439, 0.317, 0.245], spread 0.73, stray 0.137
annealed, 100 steps per level: mode weights [0.487, 0.333, 0.18], spread 0.54, stray 0.023
finest level only, 1000 steps:  mode weights [0.385, 0.281, 0.335], spread 1.06, stray 0.491

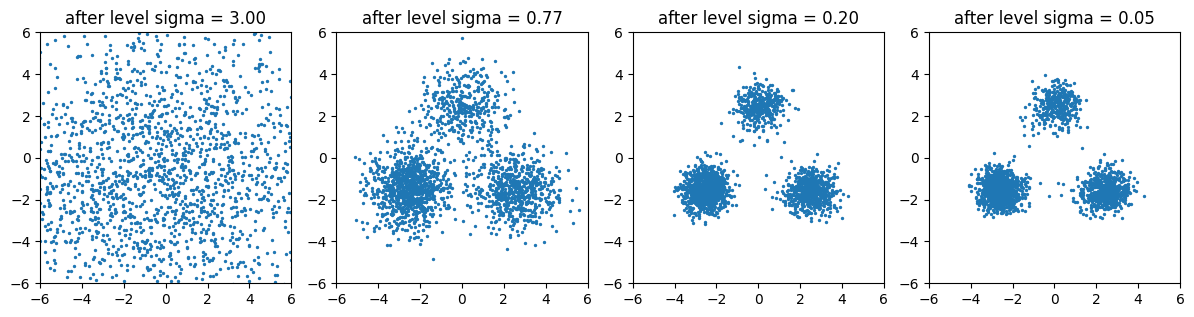
Same budget of a thousand evaluations: the annealed chain recovers the weights with a slightly wider spread and few strays; the finest level alone moves the chains only part of the way, because its steps are 3600 times smaller than those of the coarsest level.

Iterative Refinement

Proportions are settled at the coarse levels, while the modes are still broad; the fine levels only sharpen.

A U-Net Approximates the Scores at Every Level
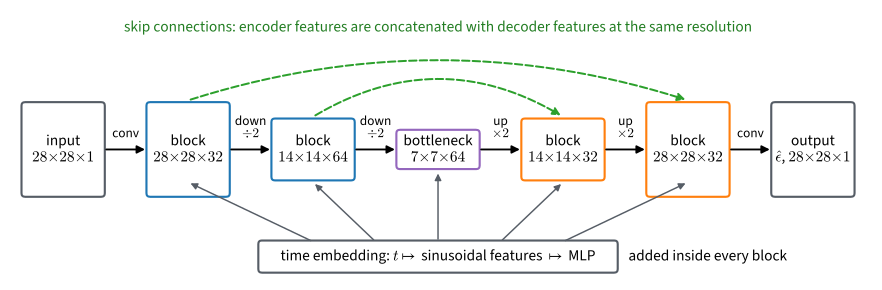
One Network Denoises at Three Levels
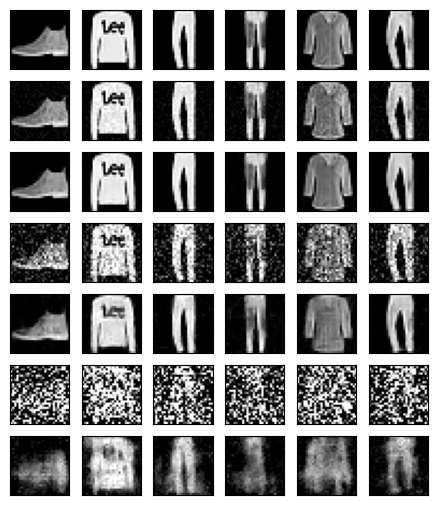
sigma = 0.09: per-pixel squared error noisy 0.009, denoised 0.003
sigma = 0.43: per-pixel squared error noisy 0.186, denoised 0.025
sigma = 2.00: per-pixel squared error noisy 4.001, denoised 0.158

Fine level: the original. Middle: the posterior mean. Coarse: a blurred silhouette, the layout without the detail. Layout, shape, detail.

Recap

  • A noise-conditional network learns \nabla \log p_{\sigma_i} for a whole ladder, by noise prediction.
  • Annealed Langevin dynamics samples coarse to fine; each level starts from the previous level’s samples, likely where its score is well estimated.
  • Conditioning: add a classifier gradient to the score (Bayes’ rule).
  • Remaining costs: a long chain, no tractable likelihood, a ladder rather than a process. Next: diffusion models.